Smart Testing in KM
Watch the tutorial
Overview
Smart Testing is a powerful feature that enables users to leverage LLMs for generating, executing, and evaluating test queries within Leena AI's Knowledge Management (KM) dashboard. It provides a seamless way to assess the accuracy of the KM agent, offering quick and valuable insights which can be further analysed to enhance its performance.
'Test queries' refers to the possible questions which users can ask from a given knowledge article in the virtual assistant.
Accessing 'Smart Testing'
Smart Testing is only accessible to KM admins.
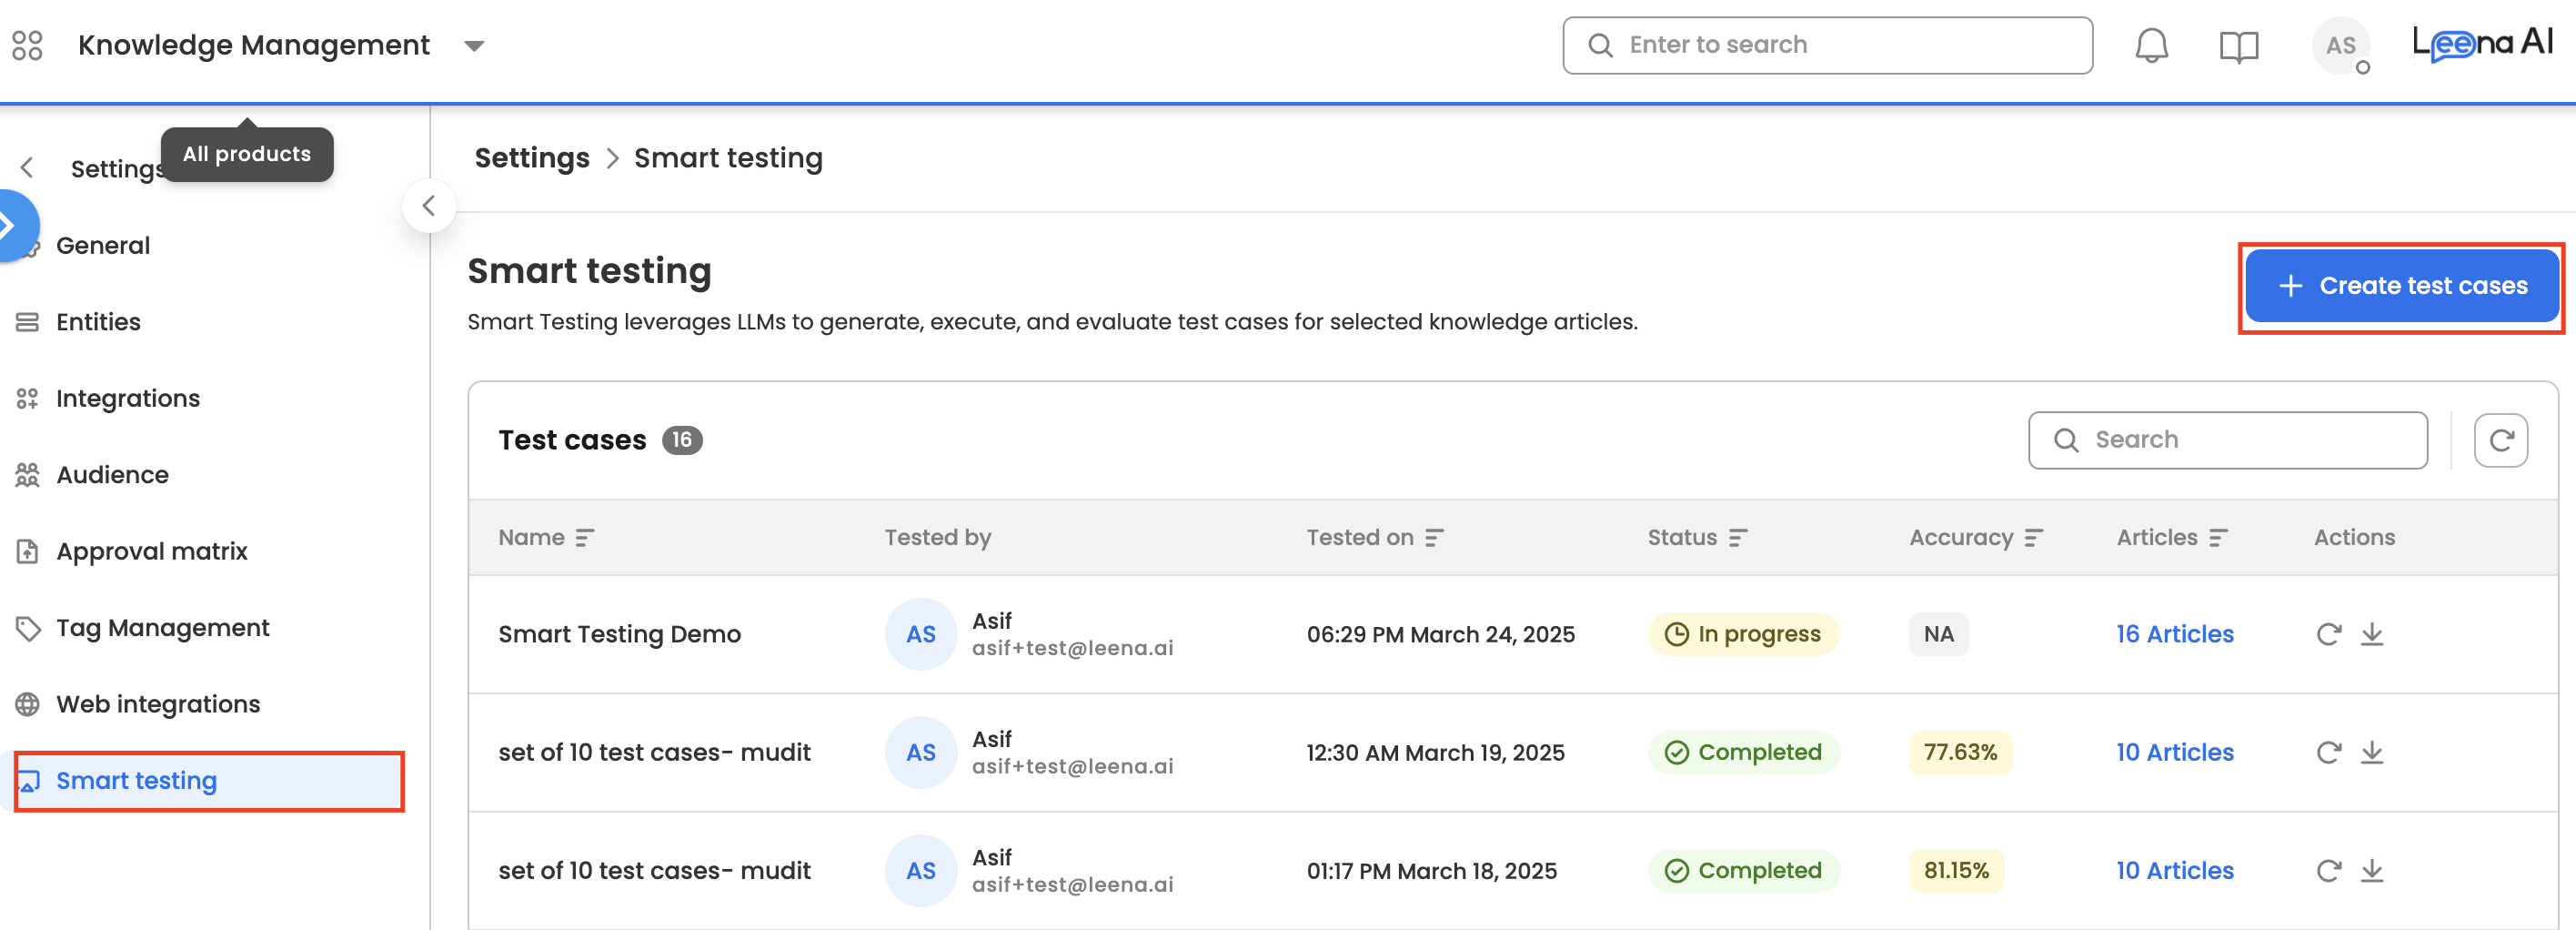
Admins can navigate to Settings >> Smart Testing.
Smart Testing Process
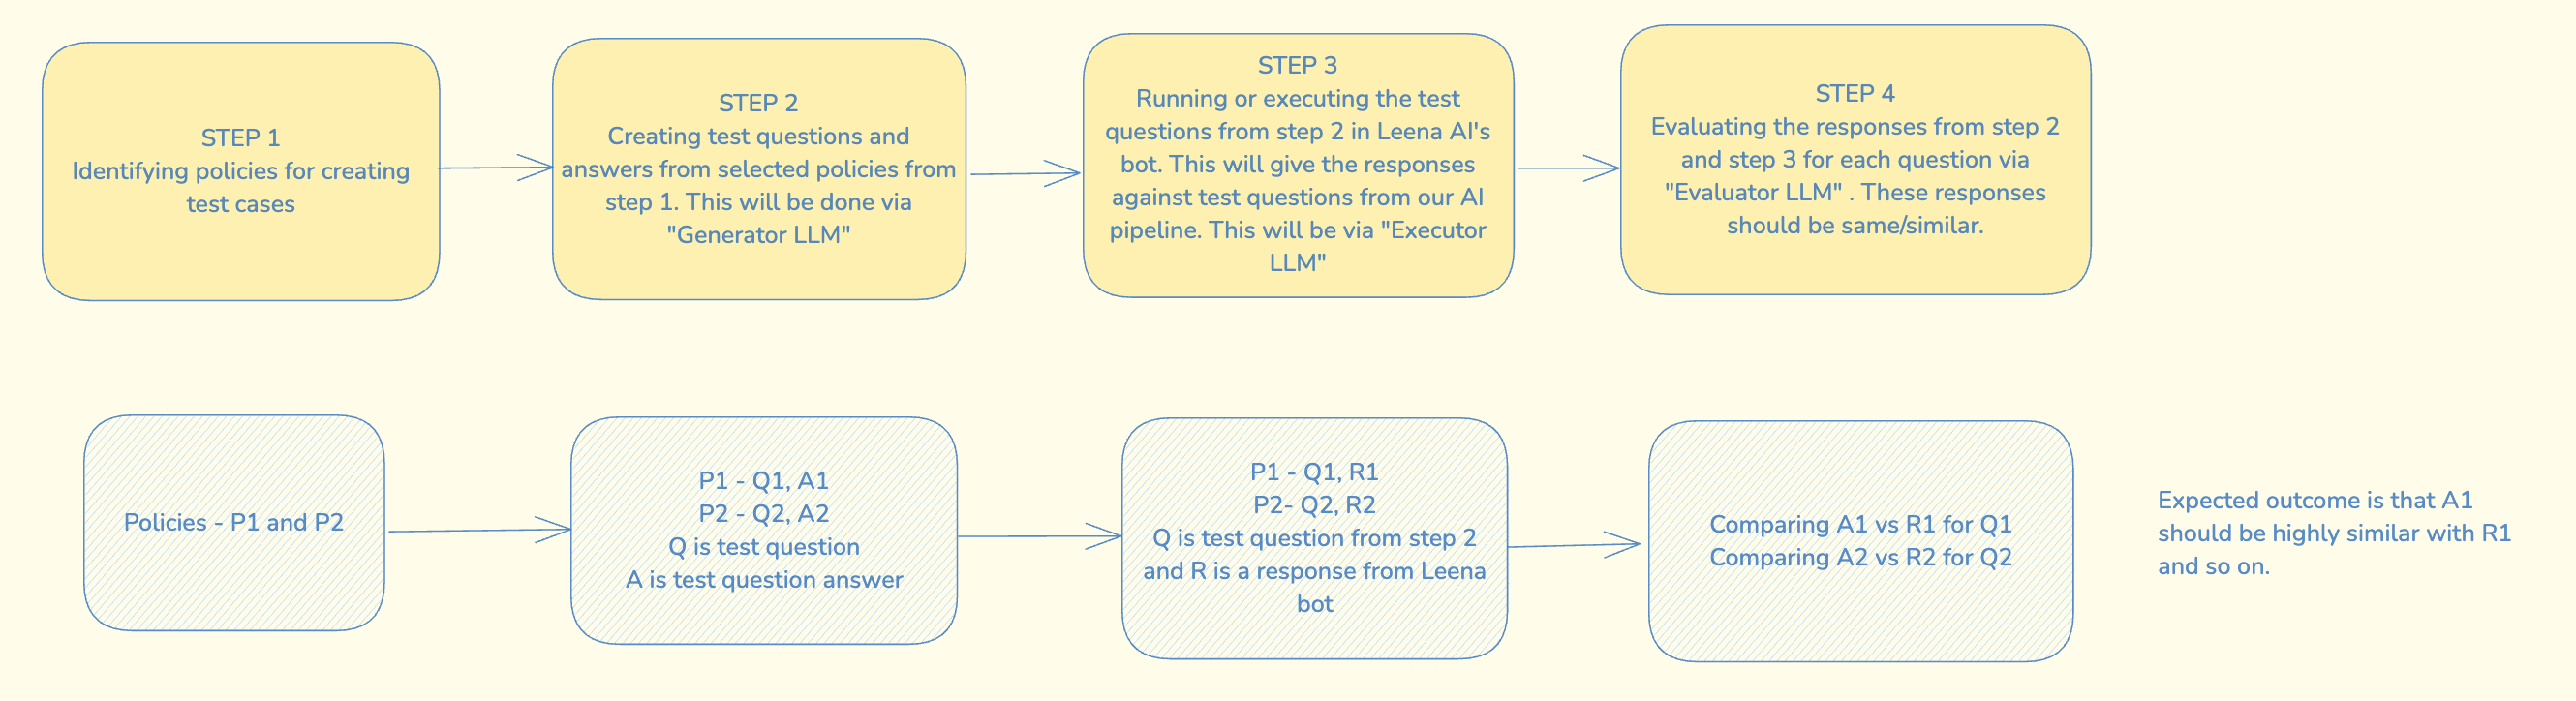
The Smart Testing workflow evaluates the accuracy of Leena AI's KM system using Large Language Models (LLMs). Here's a breakdown of each component:
Step-by-Step Explanation
-
STEP 1: Identifying Policies for Test Cases
- The first step involves selecting relevant policies (e.g., P1, P2) from the knowledge base.
- These policies will be used to create test cases, ensuring the chatbot's responses align with predefined knowledge.
-
STEP 2: Generating Test Questions and Answers
-
A Generator LLM is used to create test questions (Q) and expected answers (A) based on the selected policies.
-
Example:
P1 → Q1, A1P2 → Q2, A2
-
Here, Q is a test question, and A is the expected correct response based on the policy.
Note on Query Generation: To optimize processing speed and manage operational costs, the system is designed to pick random, representative queries from a document rather than generating questions for every single page. For large documents (e.g., 50+ pages), the LLM will select a subset of slides/pages to test. -
Importance Logic: The system uses AI to categorize articles. "Important" articles (like vacation policies or benefits) generate up to 20 questions, while "less important" articles (like technical docs or audit reports) may generate only 2 questions.
-
HTML Support: HTML articles are supported.
-
Generation Constraints:
PDFs: Are broken into 2-page chunks. Chunks are randomly selected if the document is too large to stay under the 20-question limit.
HTML: Limited to 10 sections per page, 200 words per section, and a maximum of 5,000 words total per article.
-
-
STEP 3: Executing Test Questions on Leena AI's Bot
- The generated test questions (Q1, Q2) are input into the Leena AI bot.
- The bot processes these queries and provides responses (R1, R2).
- An Executor LLM is used to simulate real user interactions and collect responses from the AI pipeline.
- Example:
P1 → Q1 → Bot Response: R1P2 → Q2 → Bot Response: R2
-
STEP 4: Evaluating the Responses
- The Evaluator LLM compares the bot’s responses (R1, R2) with the expected answers (A1, A2).
- The goal is to measure how similar the actual responses are to the expected ones.
- Final accuracy percentage is calculated as (Total "Yes" results / 3) * 100%.
- Example:
Compare A1 vs. R1Compare A2 vs. R2
Expected Outcome
The bot’s responses (R1, R2) should be highly similar to the expected answers (A1, A2). This ensures that the AI is accurately retrieving and presenting information from the knowledge base.
Summary of Key Components
| Component | Explanation |
|---|---|
| Policies (P1, P2) | Knowledge base policies used to generate test cases. |
| Generator LLM | Creates test questions (Q) and expected answers (A). |
| Executor LLM | Runs test questions on the bot and collects responses (R). |
| Evaluator LLM | Compares the bot's responses (R) with expected answers (A). |
| Expected Outcome | Bot responses should match expected answers, ensuring accuracy. |
Creating a Test Case
- Navigate to 'Smart Testing' in the KM dashboard.
- Click on the "Create test cases" CTA.
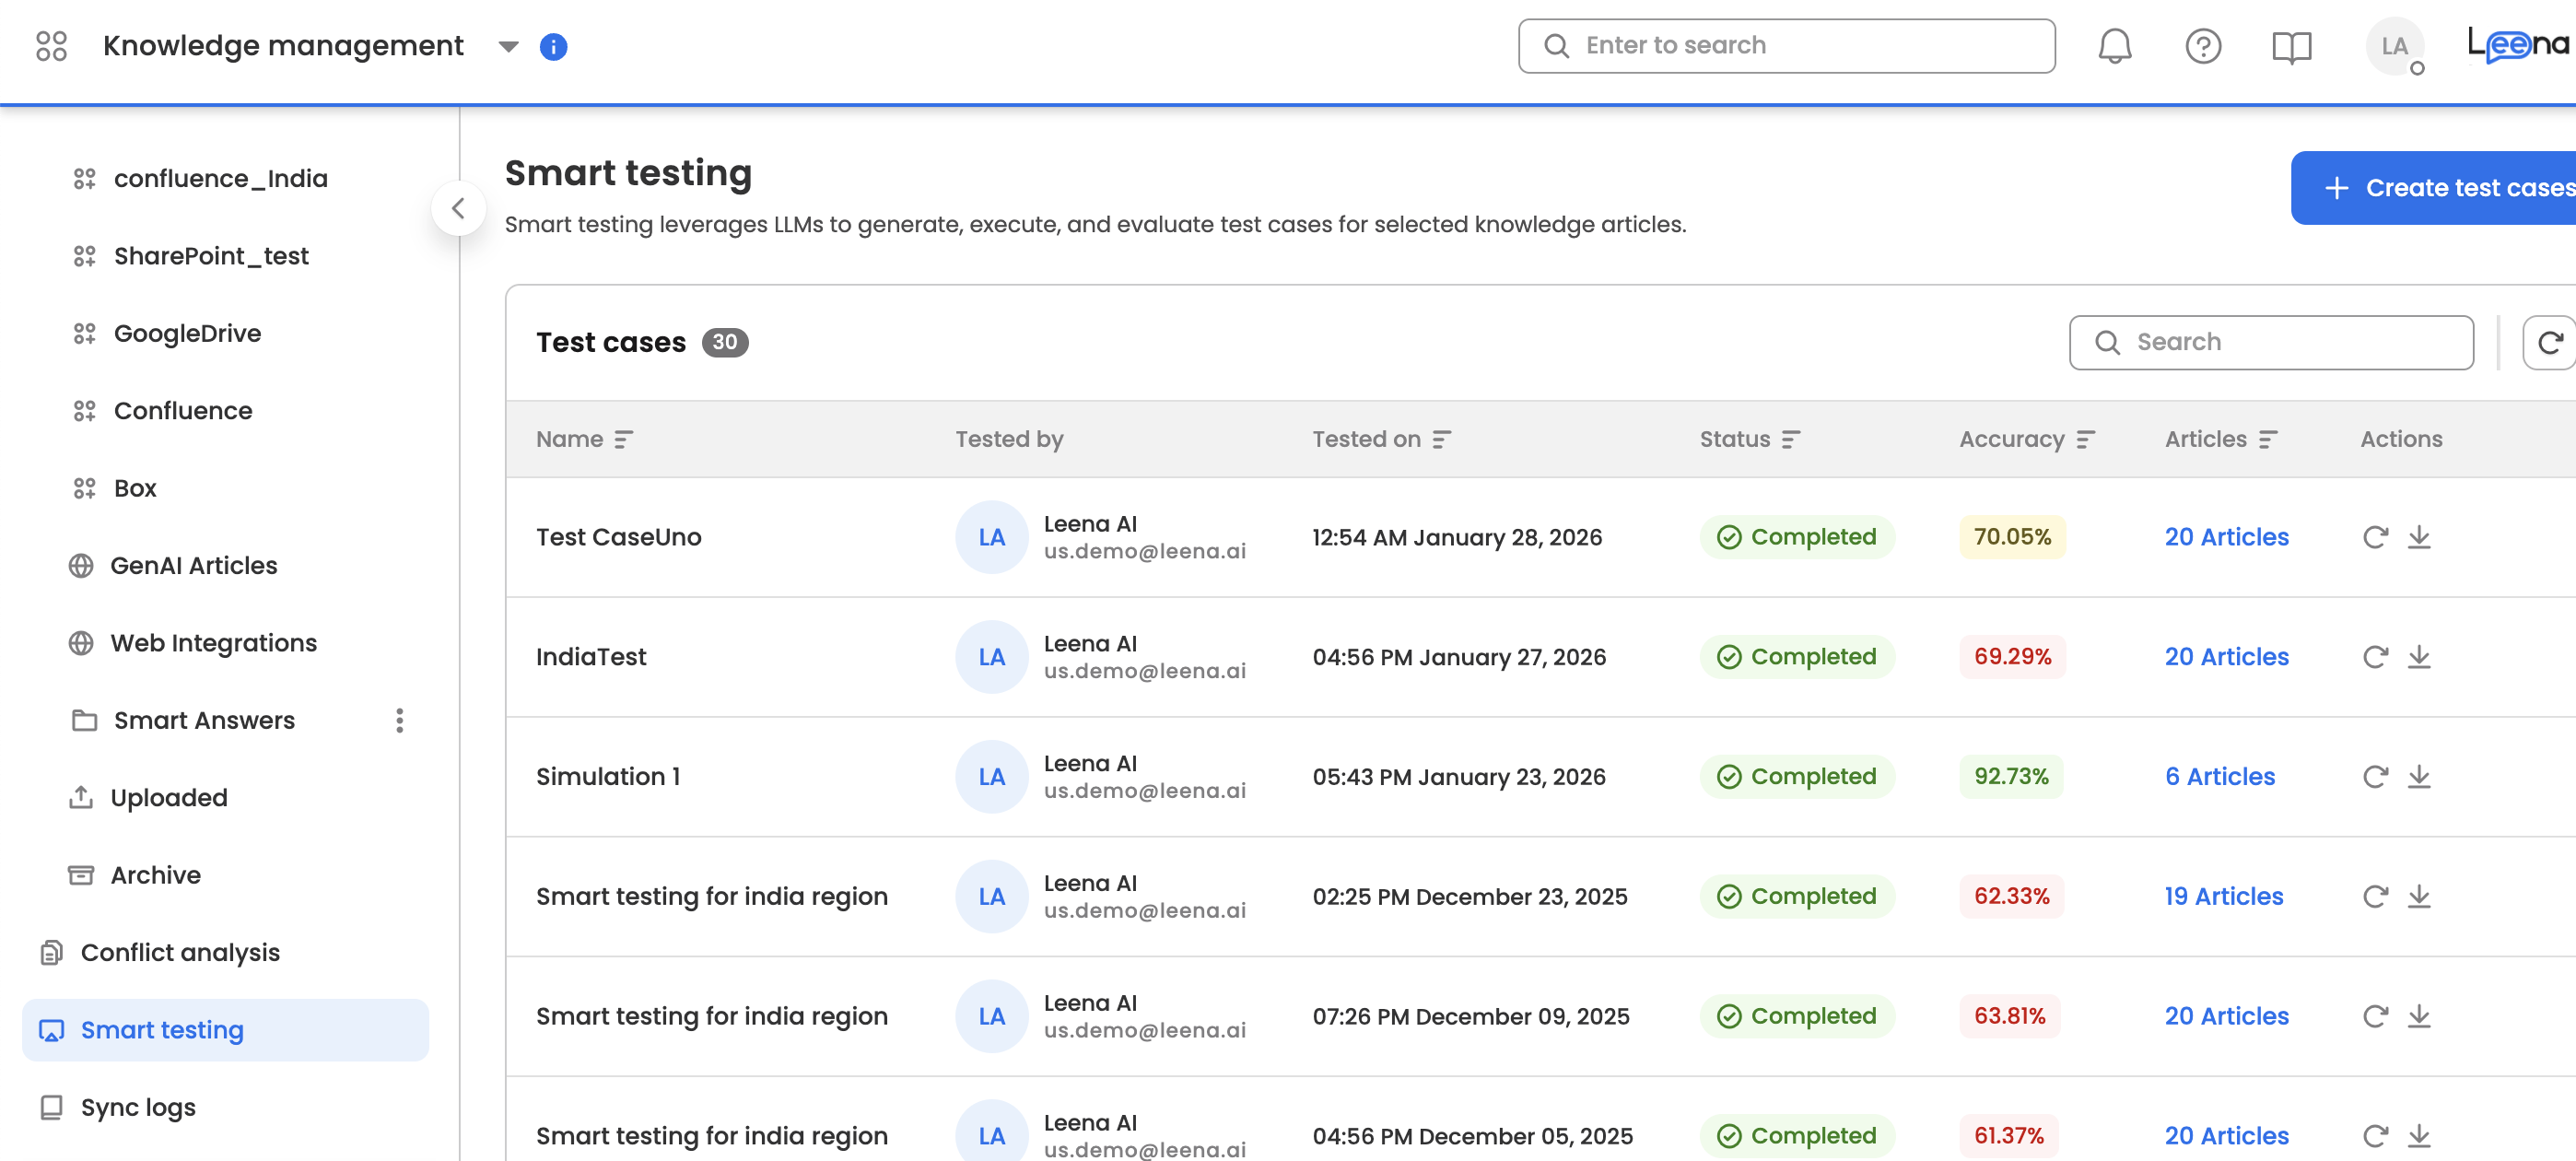
- Select the articles on which you want to generate the accuracy report. Users can also click on the row to view the articles.
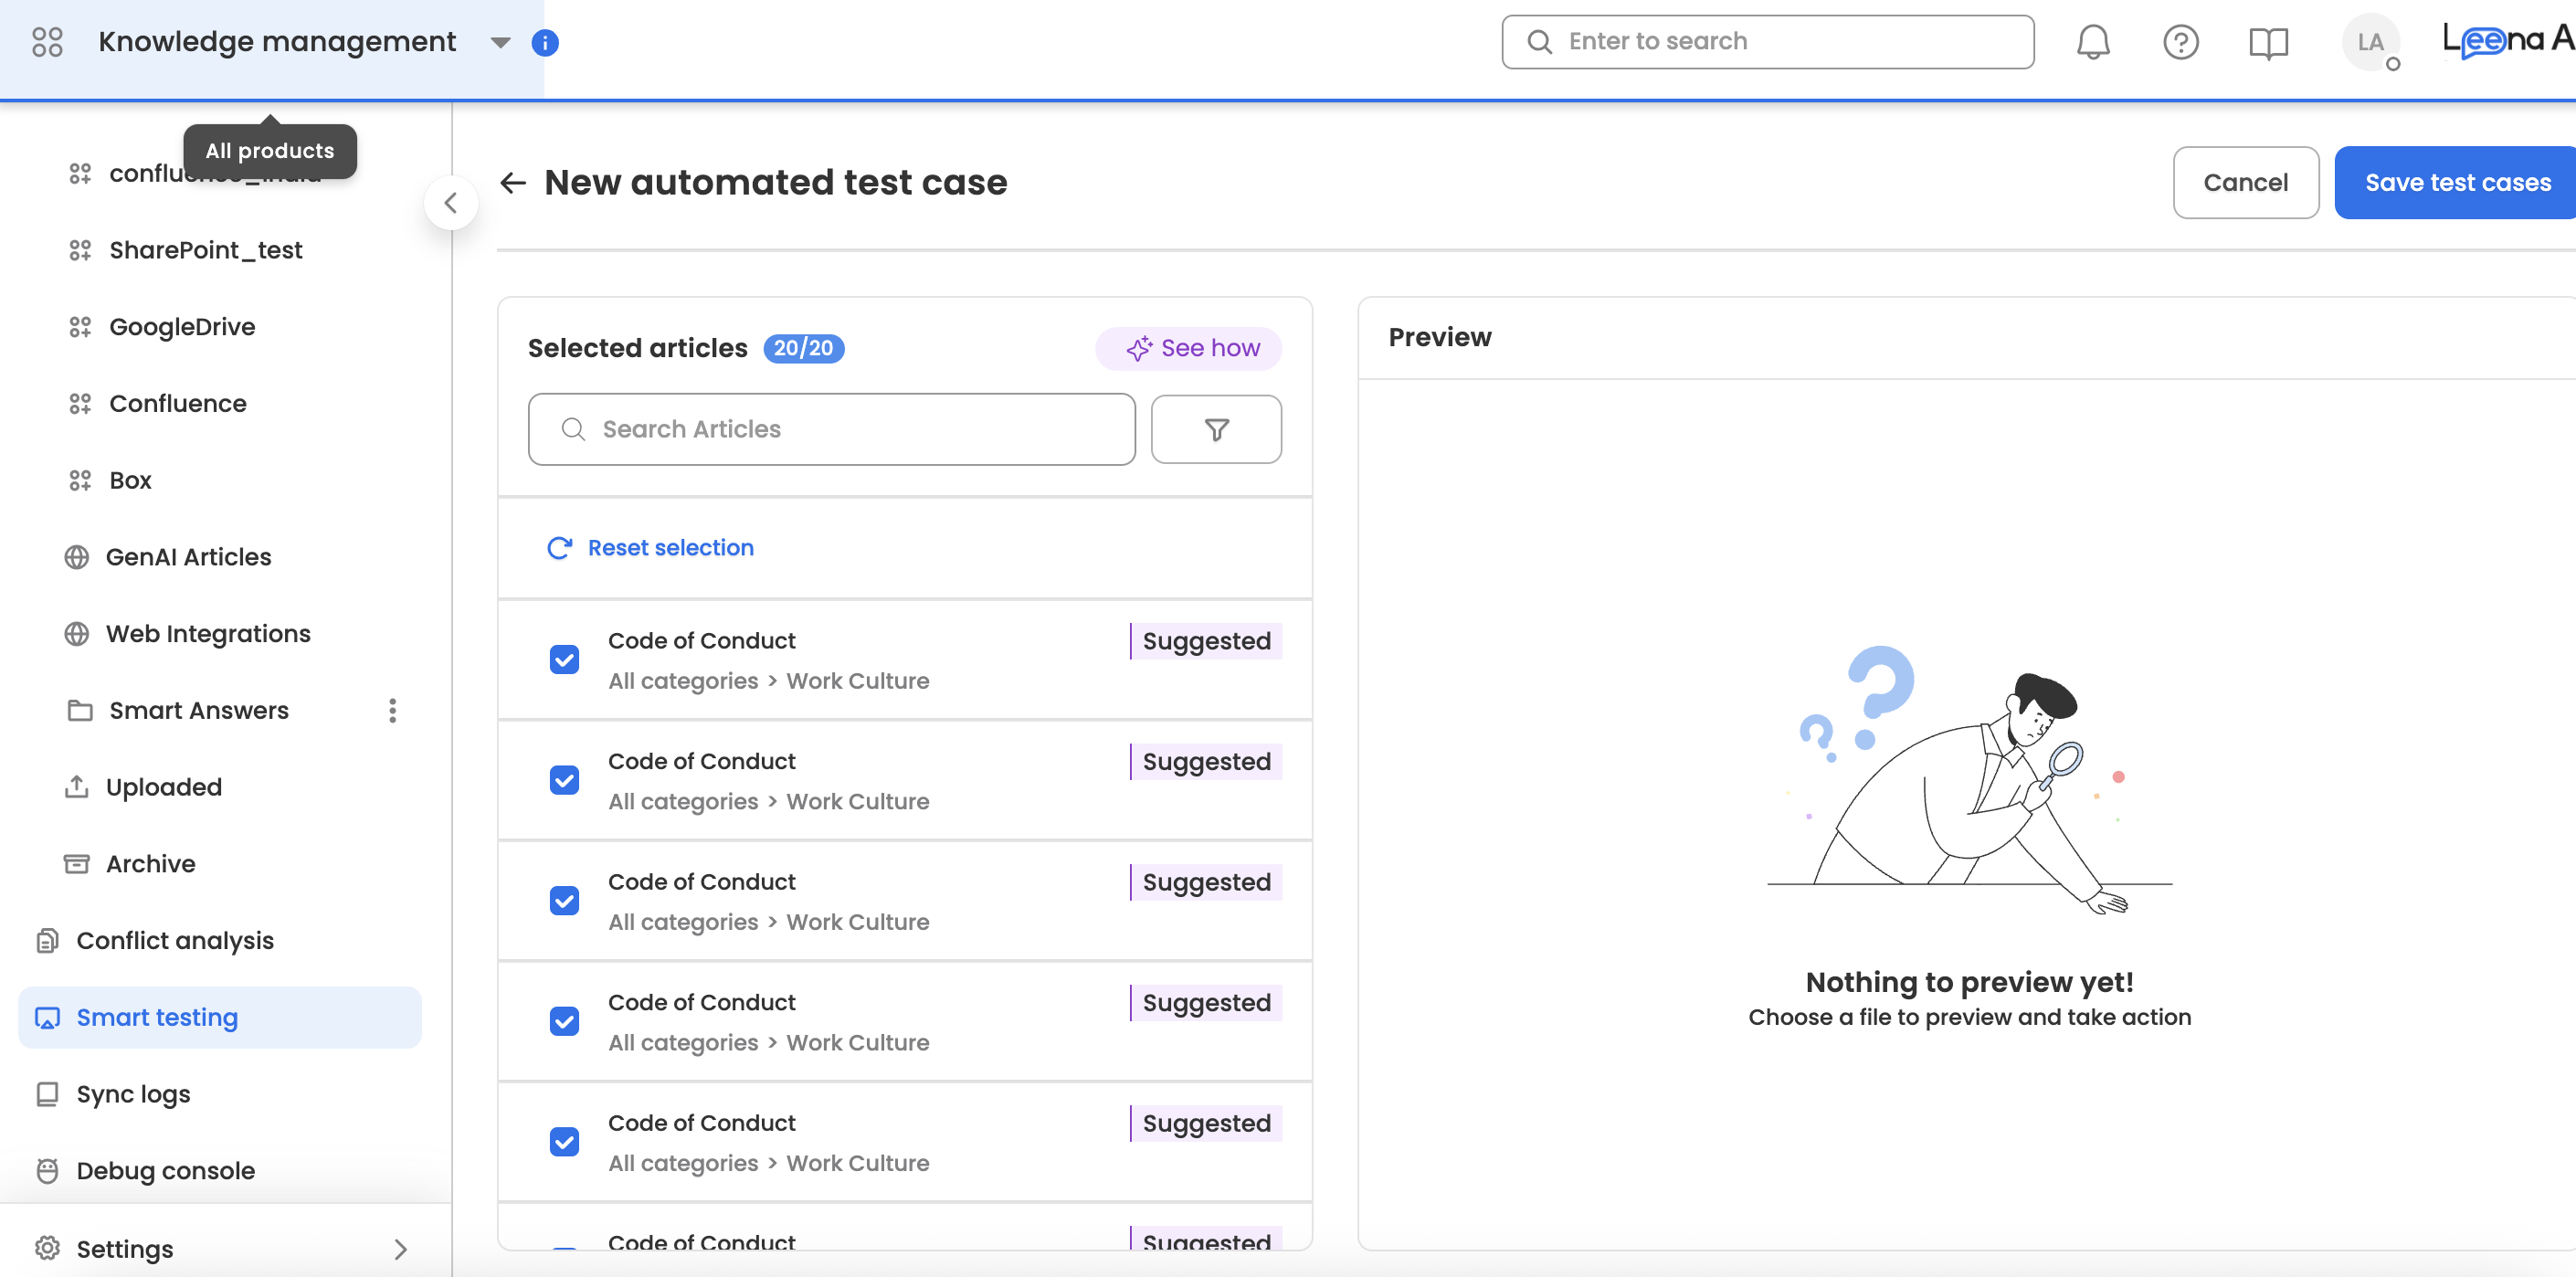
- Submit the selection.
The report is emailed to you once processed, and can also be downloaded from the dashboard. Processing time depends on the number and size of articles. Use the reload button to re-run a previous test case.
Selecting articles that have already been tested
Any published, eligible article can be selected for any run, any number of times. Participation in an earlier run does not remove an article from the picker.
-
Articles that have appeared in a previous run are marked with a previously tested icon in both the suggested list and the search/browse list.
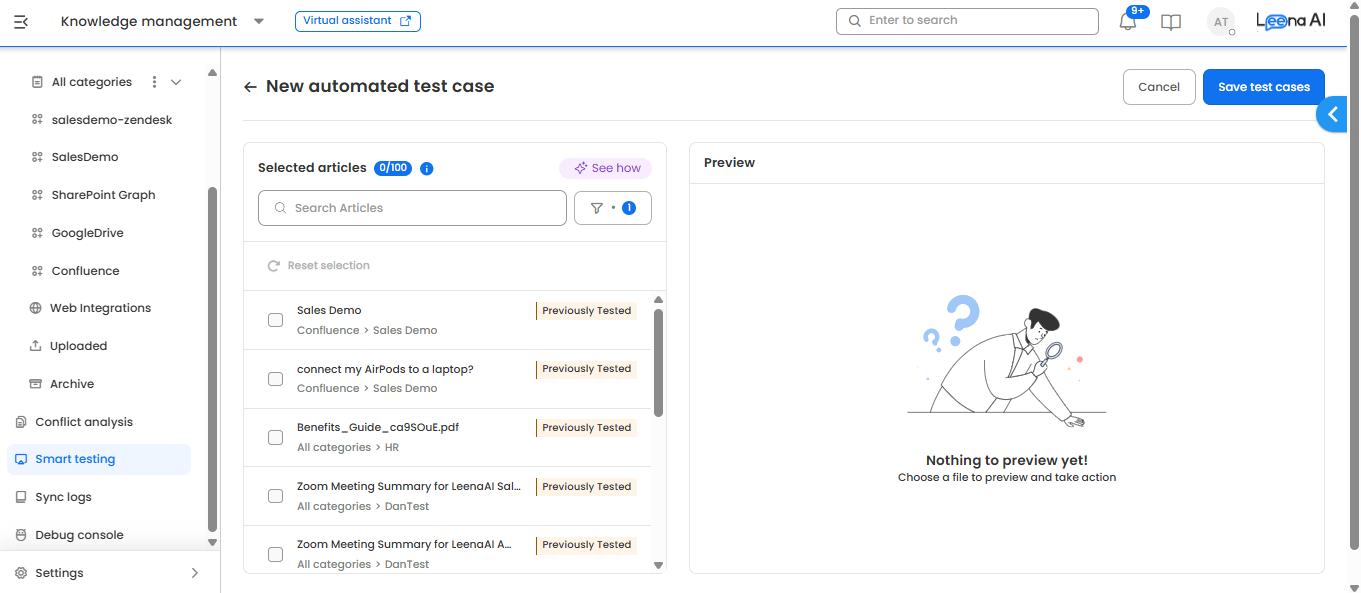
-
A previously tested filter is available, so a run can be composed of only new articles, only articles already benchmarked, or any mix.
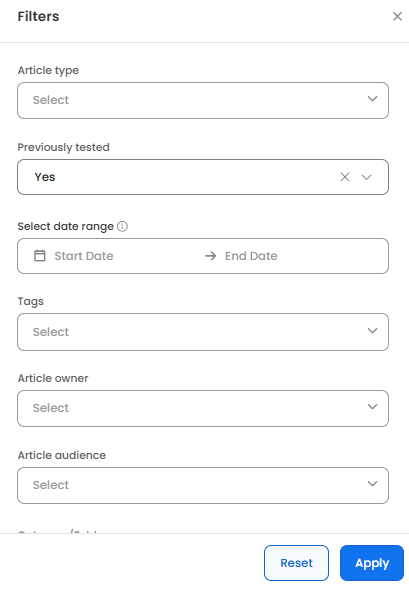
-
The indicator is informational. It does not restrict selection, and it does not change how the run is generated or evaluated.
This supports the workflows Smart Testing is intended for:
| Workflow | What it looks like |
|---|---|
| Verifying a fix | An article scored poorly, the source document was corrected and re-synced — re-run the same article to confirm the fix. |
| Regression checking | After a configuration or model change, re-run a previously used set and compare against the earlier score. |
| Composing overlapping sets | Run a broad baseline, then a focused run on one folder or document type that overlaps with the baseline. |
| Tracking accuracy over time | Repeat the same benchmark set on a regular cadence. |
Re-testing an unchanged documentWhere a document is re-tested without any change to its content, the system reuses the questions generated previously rather than generating new ones. Answers are re-fetched from the bot and re-evaluated, so the run still reflects current bot behaviour — but the question set will be identical to the earlier run. To test against a fresh set of questions, modify the source document and re-sync it before the run.
Notes: This feature tests the accuracy of the KM agent only. It is restricted to pdf, docx, html and ppt article types — spreadsheet articles (xlsx) are not eligible and do not appear in the article picker. Smart Testing does not cover personalised queries; it asks direct questions from the knowledge articles.
System limits & constraints
- Execution limit: a maximum of 1,000 test cases per day, cumulative across all users on the account.
- User concurrency: only one user per account can run a Smart Testing session at a time.
- Article limit: up to 100 articles in a single test run.
Decoding the Accuracy Report
-
Article Id: the unique id of the article in KM.
-
Article Name: the name of the article in KM.
-
Question: the LLM-generated test question from the given article.
-
Answer: the LLM-generated response for the test question — in ideal scenarios, the expected response in the bot.
-
Sources: the source articles for the bot response.
-
AI Answer: the bot response for the test question. In ideal scenarios, this should be similar to the LLM-generated answer.
-
Status: the processing status of the question.
-
Accuracy: the calculated accuracy for the given bot response. There are 3 evaluation criteria the bot response needs to pass to be 100%:
- Content Accuracy: does the actual response contain accurate information that matches the facts presented in the acceptable response?
- Completeness: does the actual response cover most of the key points and details found in the acceptable response?
- Relevance of Information: does the actual response avoid introducing unnecessary or irrelevant information?
A response passing all 3 criteria is 100% accurate; 2 criteria is 66%; 1 criterion is 33%; none is 0%. Overall accuracy is the average across all queries.
-
Content Accuracy / Completeness / Relevance: the status of each evaluation criterion.
-
Content Accuracy Reason / Completeness Reason / Relevance Reason: the LLM reasoning behind each evaluation.
-
Error: present where there is a system error in test case evaluation.
Troubleshooting
Test case stuck in "Processing". If a document remains in the processing state for more than 2 hours, it may prevent further test cases from executing.
Workaround: contact the backend team (via your designated POC) to manually cancel the stuck request. Once cancelled, a new test case can be initiated.
A published article is missing from the picker. Confirm the article is Published and of a supported type (pdf, docx, html, ppt). Spreadsheet articles are not eligible. Articles used in earlier runs are not excluded — where an expected article is missing for any other reason, raise it with your Leena AI POC.
Follow-up questions marked as failures. Where Allow follow-ups / ambiguity detection is enabled on the bot, clarifying questions raised by the bot during a test run are no longer counted as incorrect answers.
Updated about 1 month ago